iFANN
    Rechercher sur iFANN...
    Connexion
    Accueil
    Actualités
    Vidéos
    Photos
    GIF
    Explorer
    Sondages
    Récompenses
    iFAMOUS
    Wiki
    Animé
    Salons
    Notifications
    Messages
    Favoris
    Profil
    WikiRécompensesiFAMOUSClassementsSecteursRécompenses créateursRécompenses utilisateursConditionsConfidentialitéRègles de la communautéRetrait / DMCAAideDéveloppeurs

    © 2026 iFANN

    Accueil
    Rechercher
    Messages
    Alertes
    Profil
    Photo
    Nate
    Nate@nate_5123w
    💭Tech💭AI
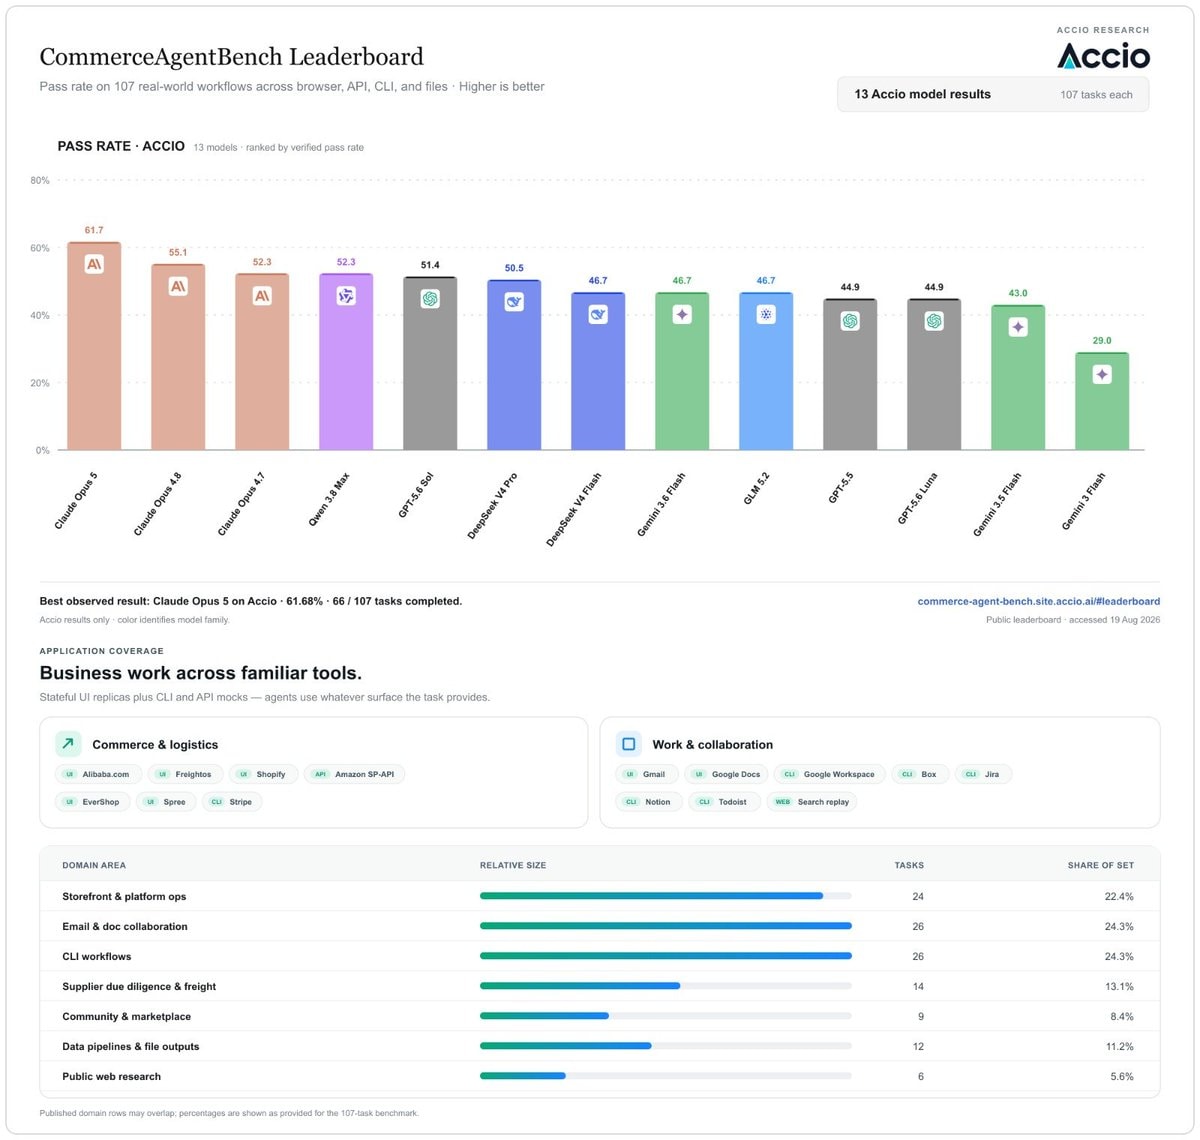
    CommerceAgentBench Leaderboard

    @nate_512There is a fundamental problem with most AI benchmarks: They evaluate outputs, while production systems depend on actions. That’s precisely the gap Accio_official’s newly open-sourced CommerceAgentBench aims to close. Take one of its procurement tasks. The agent receives roughly 300 noisy emails and has to: > verify supplier identities > reconstruct the latest valid quote > normalize currencies, Incoterms, and surcharges > compare landed costs > detect payment-redirection fraud > apply labels, save drafts, and create a kickoff calendar In other words, the task is not 'summarize this inbox':) It is rather: 'make the right procurement decisions and execute the workflow across multiple systems' .. and that distinction matters. CommerceAgentBench evaluates the operational traces the agent leaves behind: > the records it modifies > the drafts it saves > the objects it creates > and the actions it executes Its 107 tasks are grounded in real-world usage, distilled from: → 10M+ SME users → 1.6M conversations → 200K execution traces → 2,000 high-value workflows Accio itself already serves more than 10 million SMEs worldwide and draws on Alibaba’s 27 years of e-commerce experience. My take: this is a much more realistic direction for agent evaluation. In production, nobody cares that an AI produced a plausible description of the work. They care whether the work was actually completed correctly. Their benchmarks are fully open-source. Check them out in the 🧵↓ #Tech

    Voir la publication d'origine
    CommerceAgentBench Leaderboard

    Photo de @nate_512· Aug 31, 2026· Tech

    À propos de cette photo

    This is a screenshot of a leaderboard for AI models, specifically showing their pass rates on various real-world workflows. The focus is on the performance data presented in bar charts and tables. The mood is informative and analytical, with a clean, data-driven aesthetic. A notable detail is the ranking of different AI models like Claude Opus, GPT, and Gemini, with their respective pass rates displayed. The title at the top reads "CommerceAgentBench Leaderboard" and the Accio logo is visible in the top right corner.

    Voir toutes les photos de Tech

    ?

    Plus de photos de Tech

    Voir toutes les photos de Tech
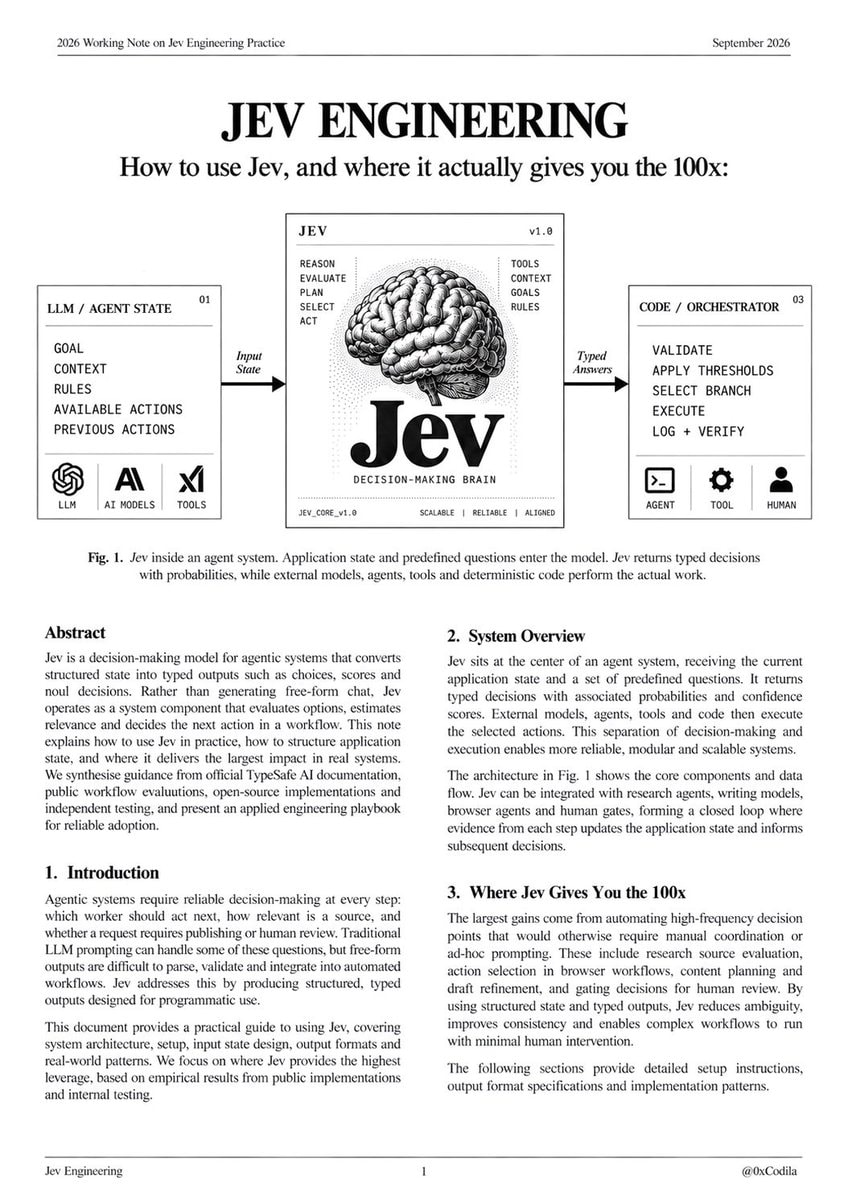
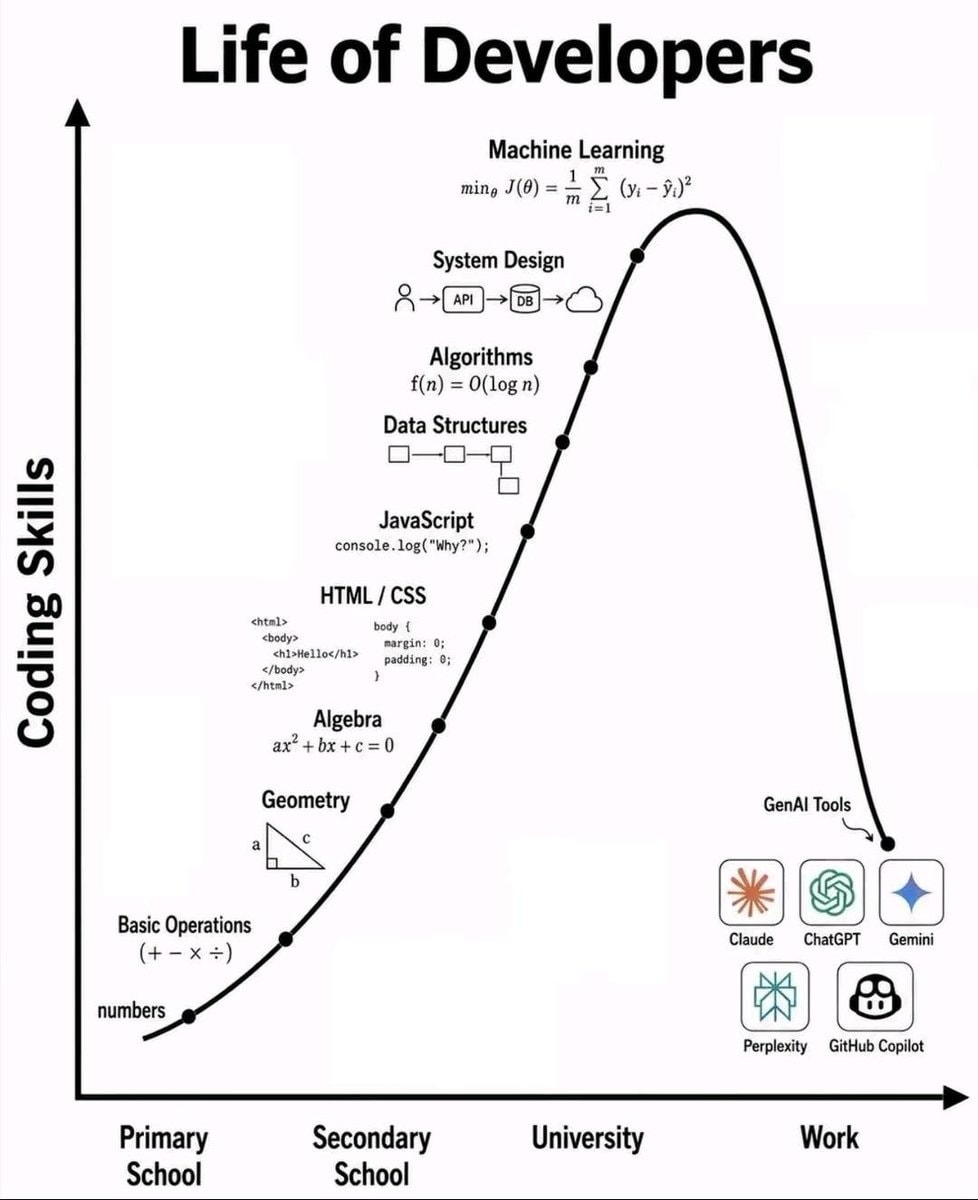
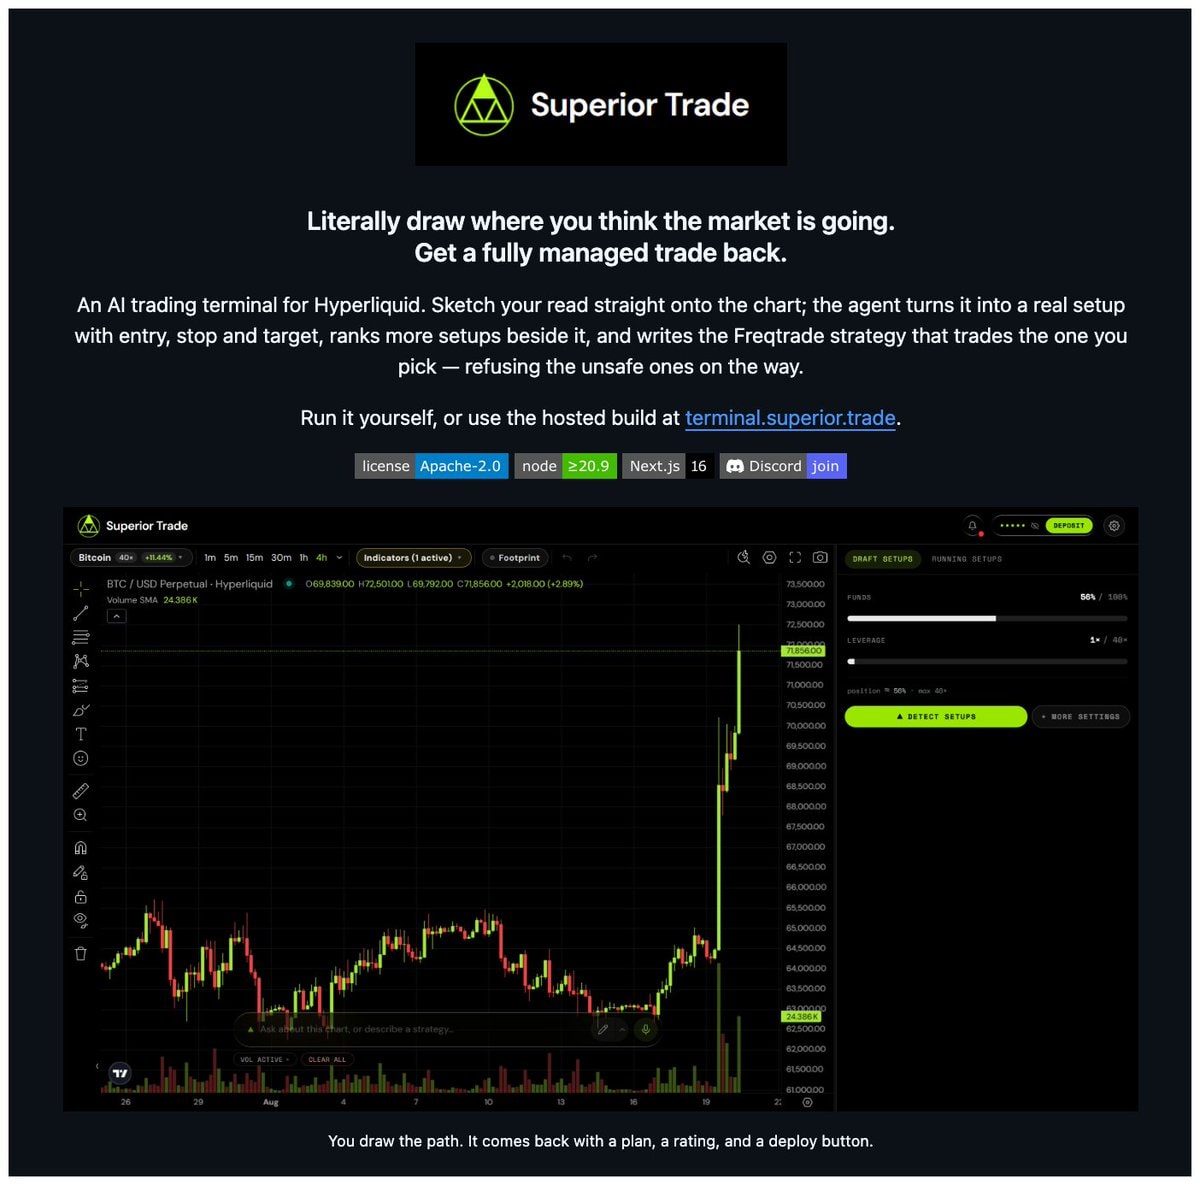
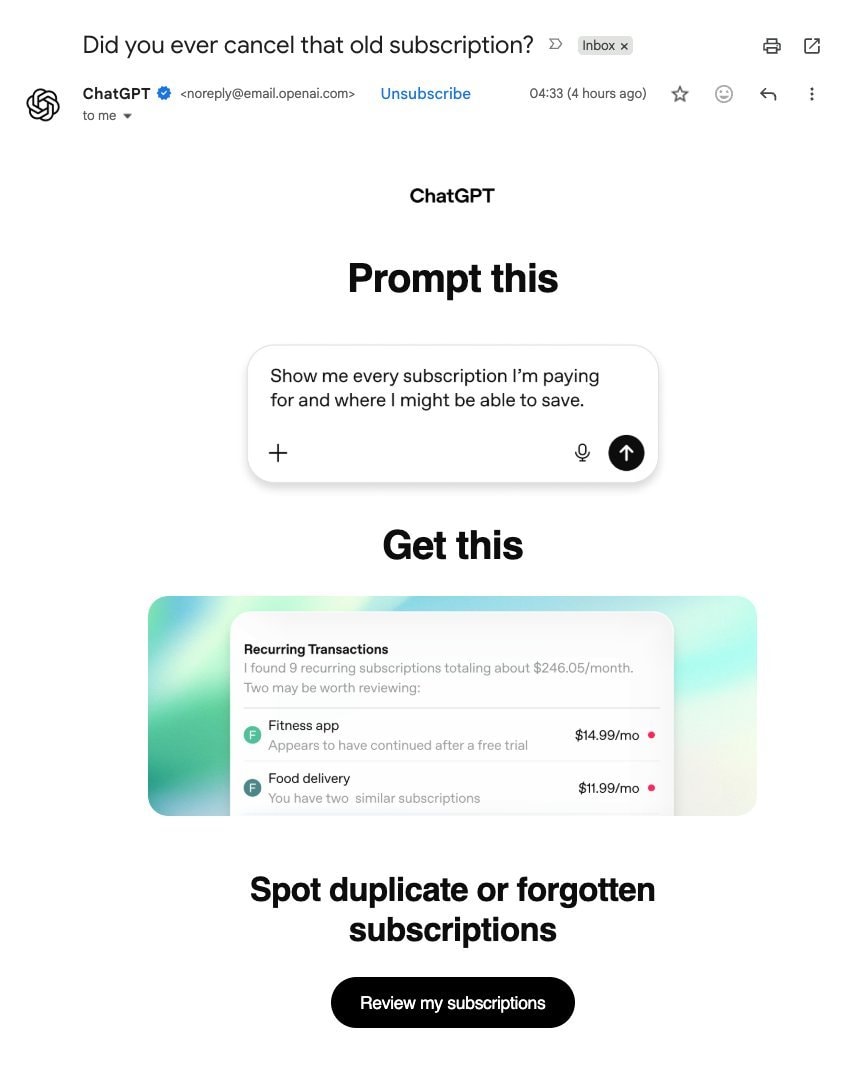
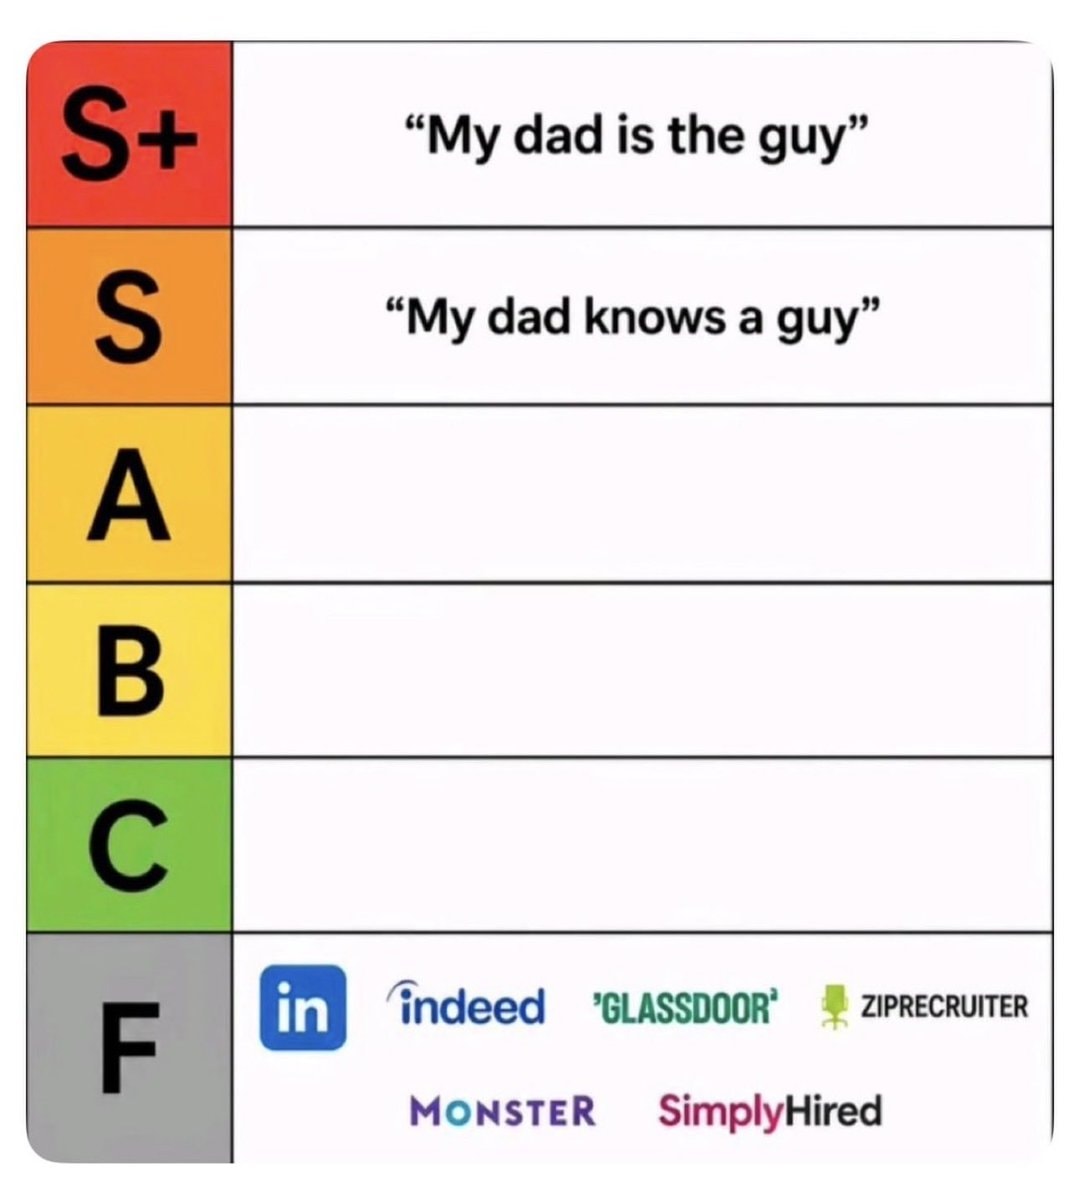
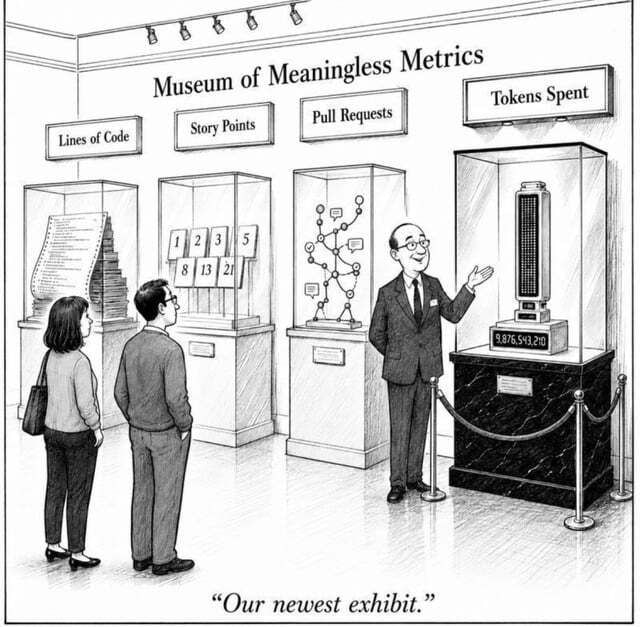
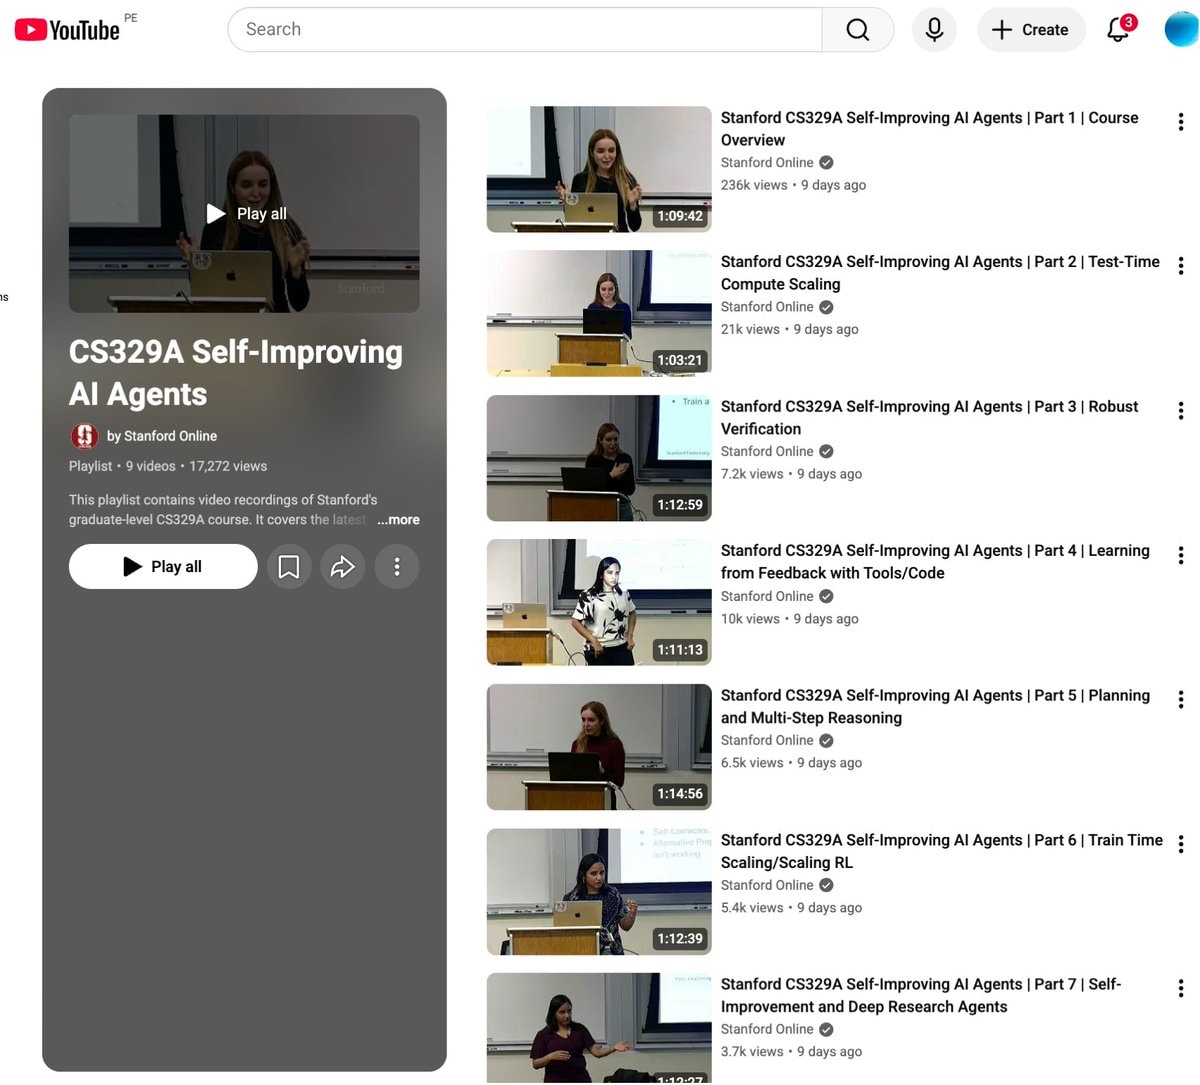
    Google WikiSkill paper SKILL.md agentsGoogle WikiSkill paper SKILL.md agentsone GOAT memeone GOAT memeaccurate memeaccurate memeJev 100x decision layer explainedJev 100x decision layer explainedLife of Developers infographicLife of Developers infographicSuperiorTrade Hyperliquid terminalSuperiorTrade Hyperliquid terminalChatGPT email screenshotChatGPT email screenshotHulk meme formatHulk meme formatVibe Coding vs Vibe Debugging memeVibe Coding vs Vibe Debugging memeAI accusation memeAI accusation memeGoogle Astra policy reactionGoogle Astra policy reactionJob portal tier list memeJob portal tier list mememuseum exhibit cartoonmuseum exhibit cartoonStanford CS329A Self-Improving AI AgentsStanford CS329A Self-Improving AI Agentsslavery to family memeslavery to family memePOLSIA founder story strategyPOLSIA founder story strategyJoe Rogan shocked reactionJoe Rogan shocked reactionCave Pro MaxCave Pro Max
    Photo
    Nate
    Nate@nate_5123w
    💭Tech💭AI
    CommerceAgentBench Leaderboard

    @nate_512There is a fundamental problem with most AI benchmarks: They evaluate outputs, while production systems depend on actions. That’s precisely the gap Accio_official’s newly open-sourced CommerceAgentBench aims to close. Take one of its procurement tasks. The agent receives roughly 300 noisy emails and has to: > verify supplier identities > reconstruct the latest valid quote > normalize currencies, Incoterms, and surcharges > compare landed costs > detect payment-redirection fraud > apply labels, save drafts, and create a kickoff calendar In other words, the task is not 'summarize this inbox':) It is rather: 'make the right procurement decisions and execute the workflow across multiple systems' .. and that distinction matters. CommerceAgentBench evaluates the operational traces the agent leaves behind: > the records it modifies > the drafts it saves > the objects it creates > and the actions it executes Its 107 tasks are grounded in real-world usage, distilled from: → 10M+ SME users → 1.6M conversations → 200K execution traces → 2,000 high-value workflows Accio itself already serves more than 10 million SMEs worldwide and draws on Alibaba’s 27 years of e-commerce experience. My take: this is a much more realistic direction for agent evaluation. In production, nobody cares that an AI produced a plausible description of the work. They care whether the work was actually completed correctly. Their benchmarks are fully open-source. Check them out in the 🧵↓ #Tech

    Voir la publication d'origine
    CommerceAgentBench Leaderboard

    Photo de @nate_512· Aug 31, 2026· Tech

    À propos de cette photo

    This is a screenshot of a leaderboard for AI models, specifically showing their pass rates on various real-world workflows. The focus is on the performance data presented in bar charts and tables. The mood is informative and analytical, with a clean, data-driven aesthetic. A notable detail is the ranking of different AI models like Claude Opus, GPT, and Gemini, with their respective pass rates displayed. The title at the top reads "CommerceAgentBench Leaderboard" and the Accio logo is visible in the top right corner.

    Voir toutes les photos de Tech

    ?

    Plus de photos de Tech

    Voir toutes les photos de Tech
    Google WikiSkill paper SKILL.md agentsGoogle WikiSkill paper SKILL.md agentsone GOAT memeone GOAT memeaccurate memeaccurate memeJev 100x decision layer explainedJev 100x decision layer explainedLife of Developers infographicLife of Developers infographicSuperiorTrade Hyperliquid terminalSuperiorTrade Hyperliquid terminalChatGPT email screenshotChatGPT email screenshotHulk meme formatHulk meme formatVibe Coding vs Vibe Debugging memeVibe Coding vs Vibe Debugging memeAI accusation memeAI accusation memeGoogle Astra policy reactionGoogle Astra policy reactionJob portal tier list memeJob portal tier list mememuseum exhibit cartoonmuseum exhibit cartoonStanford CS329A Self-Improving AI AgentsStanford CS329A Self-Improving AI Agentsslavery to family memeslavery to family memePOLSIA founder story strategyPOLSIA founder story strategyJoe Rogan shocked reactionJoe Rogan shocked reactionCave Pro MaxCave Pro Max